Harness 工程:在 Agent 优先的世界里用好 Codex
Over the past five months, our team has been running an experiment: building and shipping an internal beta of a software product with 0 lines of manually-written code.
过去五个月,我们团队一直在做一个实验:做出一个软件产品的内部测试版并上线,其中手写的代码是 0 行。
The product has internal daily users and external alpha testers. It ships, deploys, breaks, and gets fixed. What’s different is that every line of code—application logic, tests, CI configuration, documentation, observability, and internal tooling—has been written by Codex. We estimate that we built this in about 1/10th the time it would have taken to write the code by hand.
这个产品有每天在用的内部用户,也有外部的 alpha 测试者。它会发布、会部署、会出故障,也会被修好。不一样的地方在于,每一行代码都是 Codex 写的,包括应用逻辑、测试、CI 配置、文档、可观测性和内部工具。我们估计,花的时间大约只有手写代码的十分之一。
Humans steer. Agents execute.
人掌方向,Agent 干活。
We intentionally chose this constraint so we would build what was necessary to increase engineering velocity by orders of magnitude. We had weeks to ship what ended up being a million lines of code. To do that, we needed to understand what changes when a software engineering team’s primary job is no longer to write code, but to design environments, specify intent, and build feedback loops that allow Codex agents to do reliable work.
这个限制是我们故意给自己定的,就是要逼着自己把能让工程速度提升几个数量级的那些东西做出来。我们只有几周时间,最后交付的东西有一百万行代码。要做到这一点,就得搞清楚:当一个软件工程团队的主要工作不再是写代码,而是设计环境、说清意图、搭建能让 Codex Agent 稳定干活的反馈回路时,到底有哪些事情变了。
This post is about what we learned by building a brand new product with a team of agents—what broke, what compounded, and how to maximize our one truly scarce resource: human time and attention.
这篇文章讲的是我们带着一队 Agent 从零做一个全新产品学到的东西:哪些地方出了问题,哪些东西越积越有用,以及怎么把我们唯一真正稀缺的资源用到极致,也就是人的时间和注意力。
We started with an empty git repository从一个空的 git 仓库开始
The first commit to an empty repository landed in late August 2025.
空仓库的第一个提交是在 2025 年 8 月底。
The initial scaffold—repository structure, CI configuration, formatting rules, package manager setup, and application framework—was generated by Codex CLI using GPT‑5, guided by a small set of existing templates. Even the initial AGENTS.md file that directs agents how to work in the repository was itself written by Codex.
最初的脚手架,包括仓库结构、CI 配置、格式化规则、包管理器设置和应用框架,都是 Codex CLI 用 GPT‑5 生成的,只参考了少量现成的模板。就连告诉 Agent 在这个仓库里怎么干活的那份最初的 AGENTS.md,也是 Codex 自己写的。
There was no pre-existing human-written code to anchor the system. From the beginning, the repository was shaped by the agent.
系统里没有任何人事先写好的代码可以当锚点。这个仓库从一开始就是 Agent 塑造出来的。
Five months later, the repository contains on the order of a million lines of code across application logic, infrastructure, tooling, documentation, and internal developer utilities. Over that period, roughly 1,500 pull requests have been opened and merged with a small team of just three engineers driving Codex. This translates to an average throughput of 3.5 PRs per engineer per day, and surprisingly the throughput has increased as the team has grown to now seven engineers. Importantly, this wasn’t output for output’s sake: the product has been used by hundreds of users internally, including daily internal power users.
五个月后,仓库里已经有大约一百万行代码,覆盖应用逻辑、基础设施、工具、文档和内部开发者工具。这期间大约有 1,500 个 pull request 被创建并合并,驱动 Codex 的只是一个三人小团队。折算下来,平均每个工程师每天 3.5 个 PR。出乎意料的是,团队扩到现在的七个人之后,这个吞吐量反而提高了。而且这不是为了产出而产出:这个产品已经有几百个内部用户在用,其中有每天都用的内部重度用户。
Throughout the development process, humans never directly contributed any code. This became a core philosophy for the team: no manually-written code.
整个开发过程中,人从来没有直接贡献过代码。这成了团队的核心理念:不手写代码。
Redefining the role of the engineer重新定义工程师的角色
The lack of hands-on human coding introduced a different kind of engineering work, focused on systems, scaffolding, and leverage.
人不再亲手写代码,带来了另一种工程工作,重心在系统、脚手架和杠杆上。
Early progress was slower than we expected, not because Codex was incapable, but because the environment was underspecified. The agent lacked the tools, abstractions, and internal structure required to make progress toward high-level goals. The primary job of our engineering team became enabling the agents to do useful work.
一开始的进展比我们预想的慢,原因不是 Codex 能力不够,而是环境没交代清楚。Agent 缺少朝高层目标推进所需的工具、抽象和内部结构。于是我们工程团队的主要工作,变成了想办法让 Agent 干成有用的活。
In practice, this meant working depth-first: breaking down larger goals into smaller building blocks (design, code, review, test, etc), prompting the agent to construct those blocks, and using them to unlock more complex tasks. When something failed, the fix was almost never “try harder.” Because the only way to make progress was to get Codex to do the work, human engineers always stepped into the task and asked: “what capability is missing, and how do we make it both legible and enforceable for the agent?”
实际做起来就是深度优先:把大目标拆成更小的构建块(设计、编码、评审、测试等等),让 Agent 把这些块造出来,再用它们去解锁更复杂的任务。出了问题,解决办法几乎从来不是「再努力一点」。因为推进的唯一途径是让 Codex 去干,人类工程师总是会介入任务,问一句:「缺的是什么能力?怎么让它对 Agent 来说既看得懂、又能强制执行?」
Humans interact with the system almost entirely through prompts: an engineer describes a task, runs the agent, and allows it to open a pull request. To drive a PR to completion, we instruct Codex to review its own changes locally, request additional specific agent reviews both locally and in the cloud, respond to any human or agent given feedback, and iterate in a loop until all agent reviewers are satisfied (effectively this is a Ralph Wiggum Loop). Codex uses our standard development tools directly (gh, local scripts, and repository-embedded skills) to gather context without humans copying and pasting into the CLI.
人和系统打交道几乎全靠提示词:工程师描述一个任务,运行 Agent,让它去开一个 pull request。为了把一个 PR 推到完成,我们会让 Codex 在本地评审自己的改动,在本地和云端额外请特定的 Agent 来评审,回应人或 Agent 给出的任何反馈,然后循环迭代,直到所有 Agent 评审者都满意为止(这其实就是一个 Ralph Wiggum Loop)。Codex 直接用我们的标准开发工具(gh、本地脚本,以及仓库里自带的 skill)收集上下文,不用人往 CLI 里复制粘贴。
Humans may review pull requests, but aren’t required to. Over time, we’ve pushed almost all review effort towards being handled agent-to-agent.
人可以评审 pull request,但不是必须的。慢慢地,我们把几乎所有评审工作都推给了 Agent 之间互相处理。
Increasing application legibility让应用对 Agent 更可读
As code throughput increased, our bottleneck became human QA capacity. Because the fixed constraint has been human time and attention, we’ve worked to add more capabilities to the agent by making things like the application UI, logs, and app metrics themselves directly legible to Codex.
代码吞吐量上去之后,瓶颈变成了人做 QA 的能力。既然固定不变的约束一直是人的时间和注意力,我们就想办法给 Agent 加能力:让应用 UI、日志、应用指标这些东西本身对 Codex 直接可读。
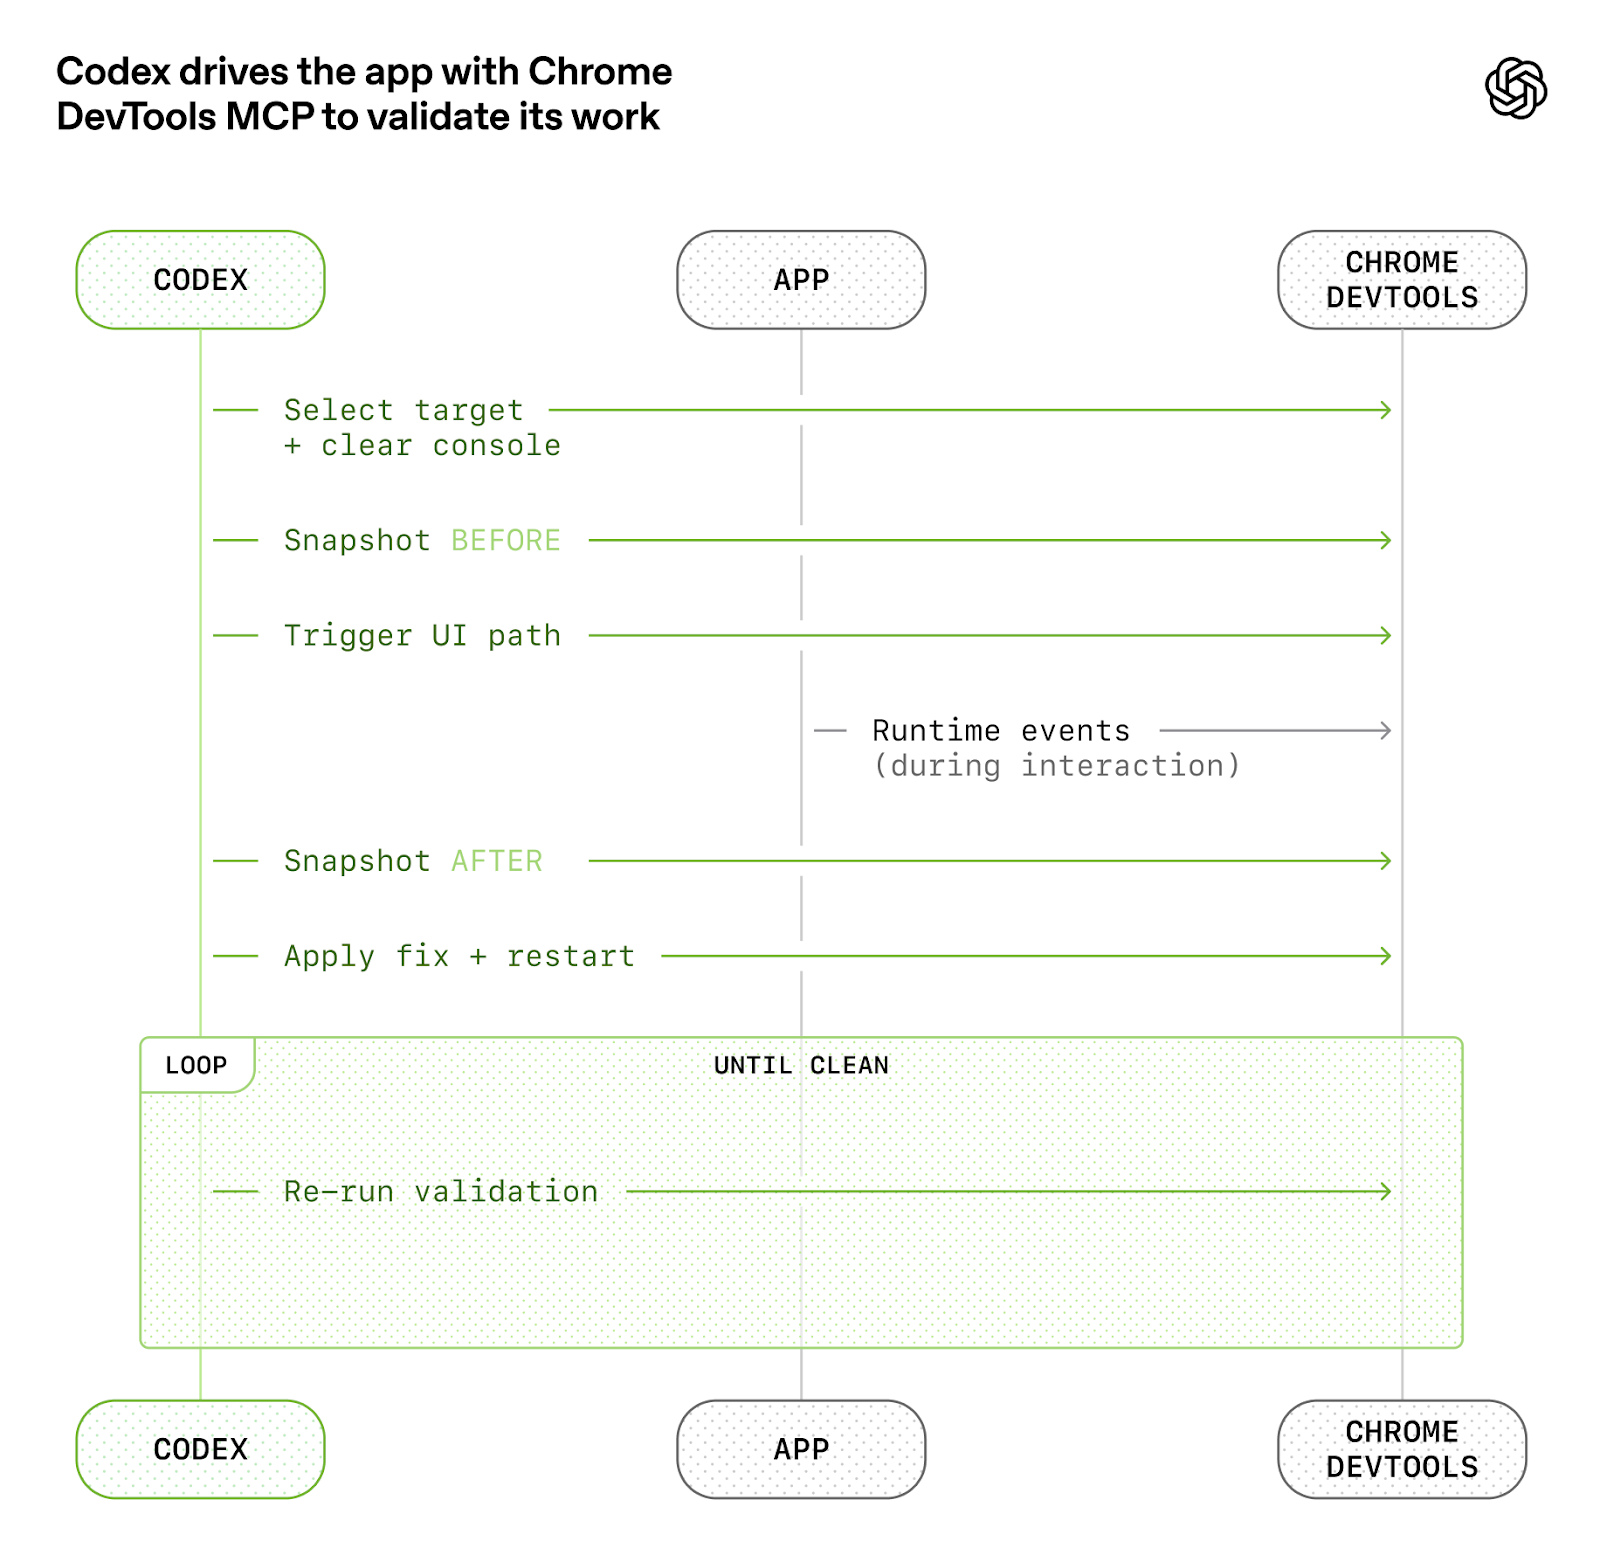
For example, we made the app bootable per git worktree, so Codex could launch and drive one instance per change. We also wired the Chrome DevTools Protocol into the agent runtime and created skills for working with DOM snapshots, screenshots, and navigation. This enabled Codex to reproduce bugs, validate fixes, and reason about UI behavior directly.
比如,我们让应用可以按 git worktree 各自启动,这样 Codex 每做一个改动就能起一个实例、自己去操作。我们还把 Chrome DevTools Protocol 接进了 Agent 的运行时,做了处理 DOM 快照、截图和页面导航的 skill。有了这些,Codex 能自己复现 bug、验证修复,直接琢磨 UI 的行为。
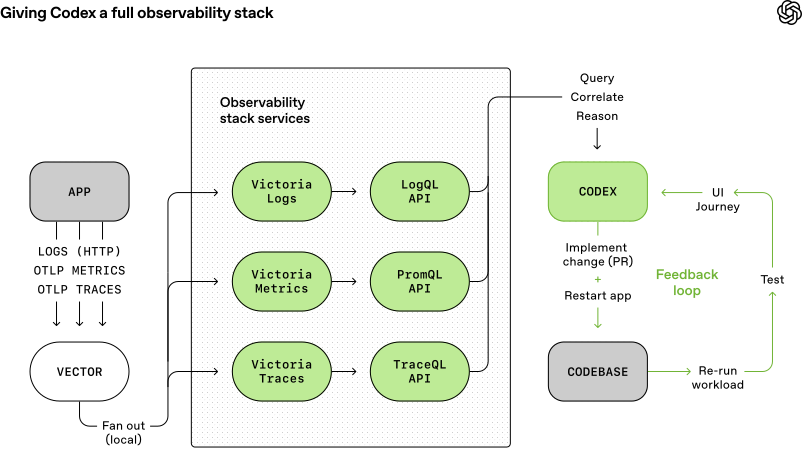
We did the same for observability tooling. Logs, metrics, and traces are exposed to Codex via a local observability stack that’s ephemeral for any given worktree. Codex works on a fully isolated version of that app—including its logs and metrics, which get torn down once that task is complete. Agents can query logs with LogQL and metrics with PromQL. With this context available, prompts like “ensure service startup completes in under 800ms” or “no span in these four critical user journeys exceeds two seconds” become tractable.
可观测性工具我们也这么做了。日志、指标和链路追踪通过一套本地可观测性栈暴露给 Codex,每个 worktree 各有一套,用完即弃。Codex 在一个完全隔离的应用副本上工作,副本的日志和指标也是独立的,任务一完成就全部销毁。Agent 可以用 LogQL 查日志、用 PromQL 查指标。有了这些上下文,「确保服务启动在 800ms 内完成」或者「这四条关键用户路径里没有哪个 span 超过两秒」这样的提示词就能落地了。
We regularly see single Codex runs work on a single task for upwards of six hours (often while the humans are sleeping).
我们经常看到一次 Codex 运行在单个任务上连续干六个多小时(往往是人在睡觉的时候)。
We made repository knowledge the system of record把仓库里的知识当作唯一可信来源
Context management is one of the biggest challenges in making agents effective at large and complex tasks. One of the earliest lessons we learned was simple: give Codex a map, not a 1,000-page instruction manual.
要让 Agent 在大型复杂任务上发挥作用,上下文管理是最大的挑战之一。我们最早学到的教训之一很简单:给 Codex 一张地图,别给它一本 1000 页的说明书。
We tried the “one big AGENTS.md” approach. It failed in predictable ways:
我们试过「一个大 AGENTS.md」的做法。它失败的方式完全在意料之中:
- Context is a scarce resource. A giant instruction file crowds out the task, the code, and the relevant docs—so the agent either misses key constraints or starts optimizing for the wrong ones.上下文是稀缺资源。一份巨大的指令文件会把任务、代码和相关文档都挤出去,结果 Agent 要么漏掉关键约束,要么开始朝错误的约束去优化。
- Too much guidance becomes non-guidance. When everything is “important,” nothing is. Agents end up pattern-matching locally instead of navigating intentionally.指导太多,就成了没有指导。什么都「重要」,就等于什么都不重要。Agent 最后只会在局部做模式匹配,不会有目的地去查找。
- It rots instantly. A monolithic manual turns into a graveyard of stale rules. Agents can’t tell what’s still true, humans stop maintaining it, and the file quietly becomes an attractive nuisance.它会马上腐烂。一本大一统的手册会变成过时规则的坟场。Agent 分不清哪些还成立,人也不再维护它,这个文件就悄悄变成了一个看着有用、实则有害的东西。
- It’s hard to verify. A single blob doesn’t lend itself to mechanical checks (coverage, freshness, ownership, cross-links), so drift is inevitable.它很难验证。一整坨文本没法做机械化的检查(覆盖率、新鲜度、归属、交叉链接),所以内容跑偏是迟早的事。
So instead of treating AGENTS.md as the encyclopedia, we treat it as the table of contents.
所以我们不再把 AGENTS.md 当百科全书,而是把它当目录。
The repository’s knowledge base lives in a structured docs/ directory treated as the system of record. A short AGENTS.md (roughly 100 lines) is injected into context and serves primarily as a map, with pointers to deeper sources of truth elsewhere.
仓库的知识库放在一个结构化的 docs/ 目录里,它就是唯一可信来源(system of record)。一份很短的 AGENTS.md(大约 100 行)会被注入上下文,主要当地图用,指向别处更深入的可信来源。
AGENTS.md
ARCHITECTURE.md
docs/
├── design-docs/
│   ├── index.md
│   ├── core-beliefs.md
│   └── ...
├── exec-plans/
│   ├── active/
│   ├── completed/
│   └── tech-debt-tracker.md
├── generated/
│   └── db-schema.md
├── product-specs/
│   ├── index.md
│   ├── new-user-onboarding.md
│   └── ...
├── references/
│   ├── design-system-reference-llms.txt
│   ├── nixpacks-llms.txt
│   ├── uv-llms.txt
│   └── ...
├── DESIGN.md
├── FRONTEND.md
├── PLANS.md
├── PRODUCT_SENSE.md
├── QUALITY_SCORE.md
├── RELIABILITY.md
└── SECURITY.md
In-repository knowledge store layout.
仓库内知识库的目录结构。
Design documentation is catalogued and indexed, including verification status and a set of core beliefs that define agent-first operating principles. Architecture documentation provides a top-level map of domains and package layering. A quality document grades each product domain and architectural layer, tracking gaps over time.
设计文档都编了目录、建了索引,包括验证状态,以及一组定义 Agent 优先运作原则的核心信念。架构文档给出领域和包分层的顶层地图。一份质量文档给每个产品领域和架构层打分,并持续跟踪其中的差距。
Plans are treated as first-class artifacts. Ephemeral lightweight plans are used for small changes, while complex work is captured in execution plans with progress and decision logs that are checked into the repository. Active plans, completed plans, and known technical debt are all versioned and co-located, allowing agents to operate without relying on external context.
计划是一等产物。小改动用临时的轻量计划;复杂的工作写进执行计划,连同进度和决策日志一起提交到仓库。进行中的计划、已完成的计划和已知的技术债都有版本管理、放在一起,Agent 不依赖外部上下文也能干活。
This enables progressive disclosure: agents start with a small, stable entry point and are taught where to look next, rather than being overwhelmed up front.
这样就做到了渐进式披露(progressive disclosure):Agent 从一个小而稳定的入口开始,被告知下一步去哪里找,而不是一上来就被信息淹没。
We enforce this mechanically. Dedicated linters and CI jobs validate that the knowledge base is up to date, cross-linked, and structured correctly. A recurring “doc-gardening” agent scans for stale or obsolete documentation that does not reflect the real code behavior and opens fix-up pull requests.
这一点我们用机械化的手段强制执行。专门的 linter 和 CI 任务会校验知识库是否最新、交叉链接是否齐全、结构是否正确。还有一个定期运行的「文档园丁」Agent,专门扫描那些过时的、和代码实际行为对不上的文档,然后开 pull request 去修。
Agent legibility is the goal目标是让 Agent 看得懂
As the codebase evolved, Codex’s framework for design decisions needed to evolve, too.
代码库在演进,Codex 做设计决策的框架也得跟着演进。
Because the repository is entirely agent-generated, it’s optimized first for Codex’s legibility. In the same way teams aim to improve navigability of their code for new engineering hires, our human engineers’ goal was making it possible for an agent to reason about the full business domain directly from the repository itself.
因为仓库完全是 Agent 生成的,它首先优化的是对 Codex 的可读性。就像团队会想办法让新入职的工程师更容易摸清代码一样,我们人类工程师的目标,是让 Agent 直接从仓库本身就能推理出整个业务领域。
From the agent’s point of view, anything it can’t access in-context while running effectively doesn’t exist. Knowledge that lives in Google Docs, chat threads, or people’s heads are not accessible to the system. Repository-local, versioned artifacts (e.g., code, markdown, schemas, executable plans) are all it can see.
从 Agent 的角度看,运行时在上下文里拿不到的东西,实际上就等于不存在。放在 Google Docs、聊天记录或者人脑子里的知识,系统都访问不到。它能看到的只有仓库本地、有版本管理的产物(比如代码、markdown、schema、可执行的计划)。
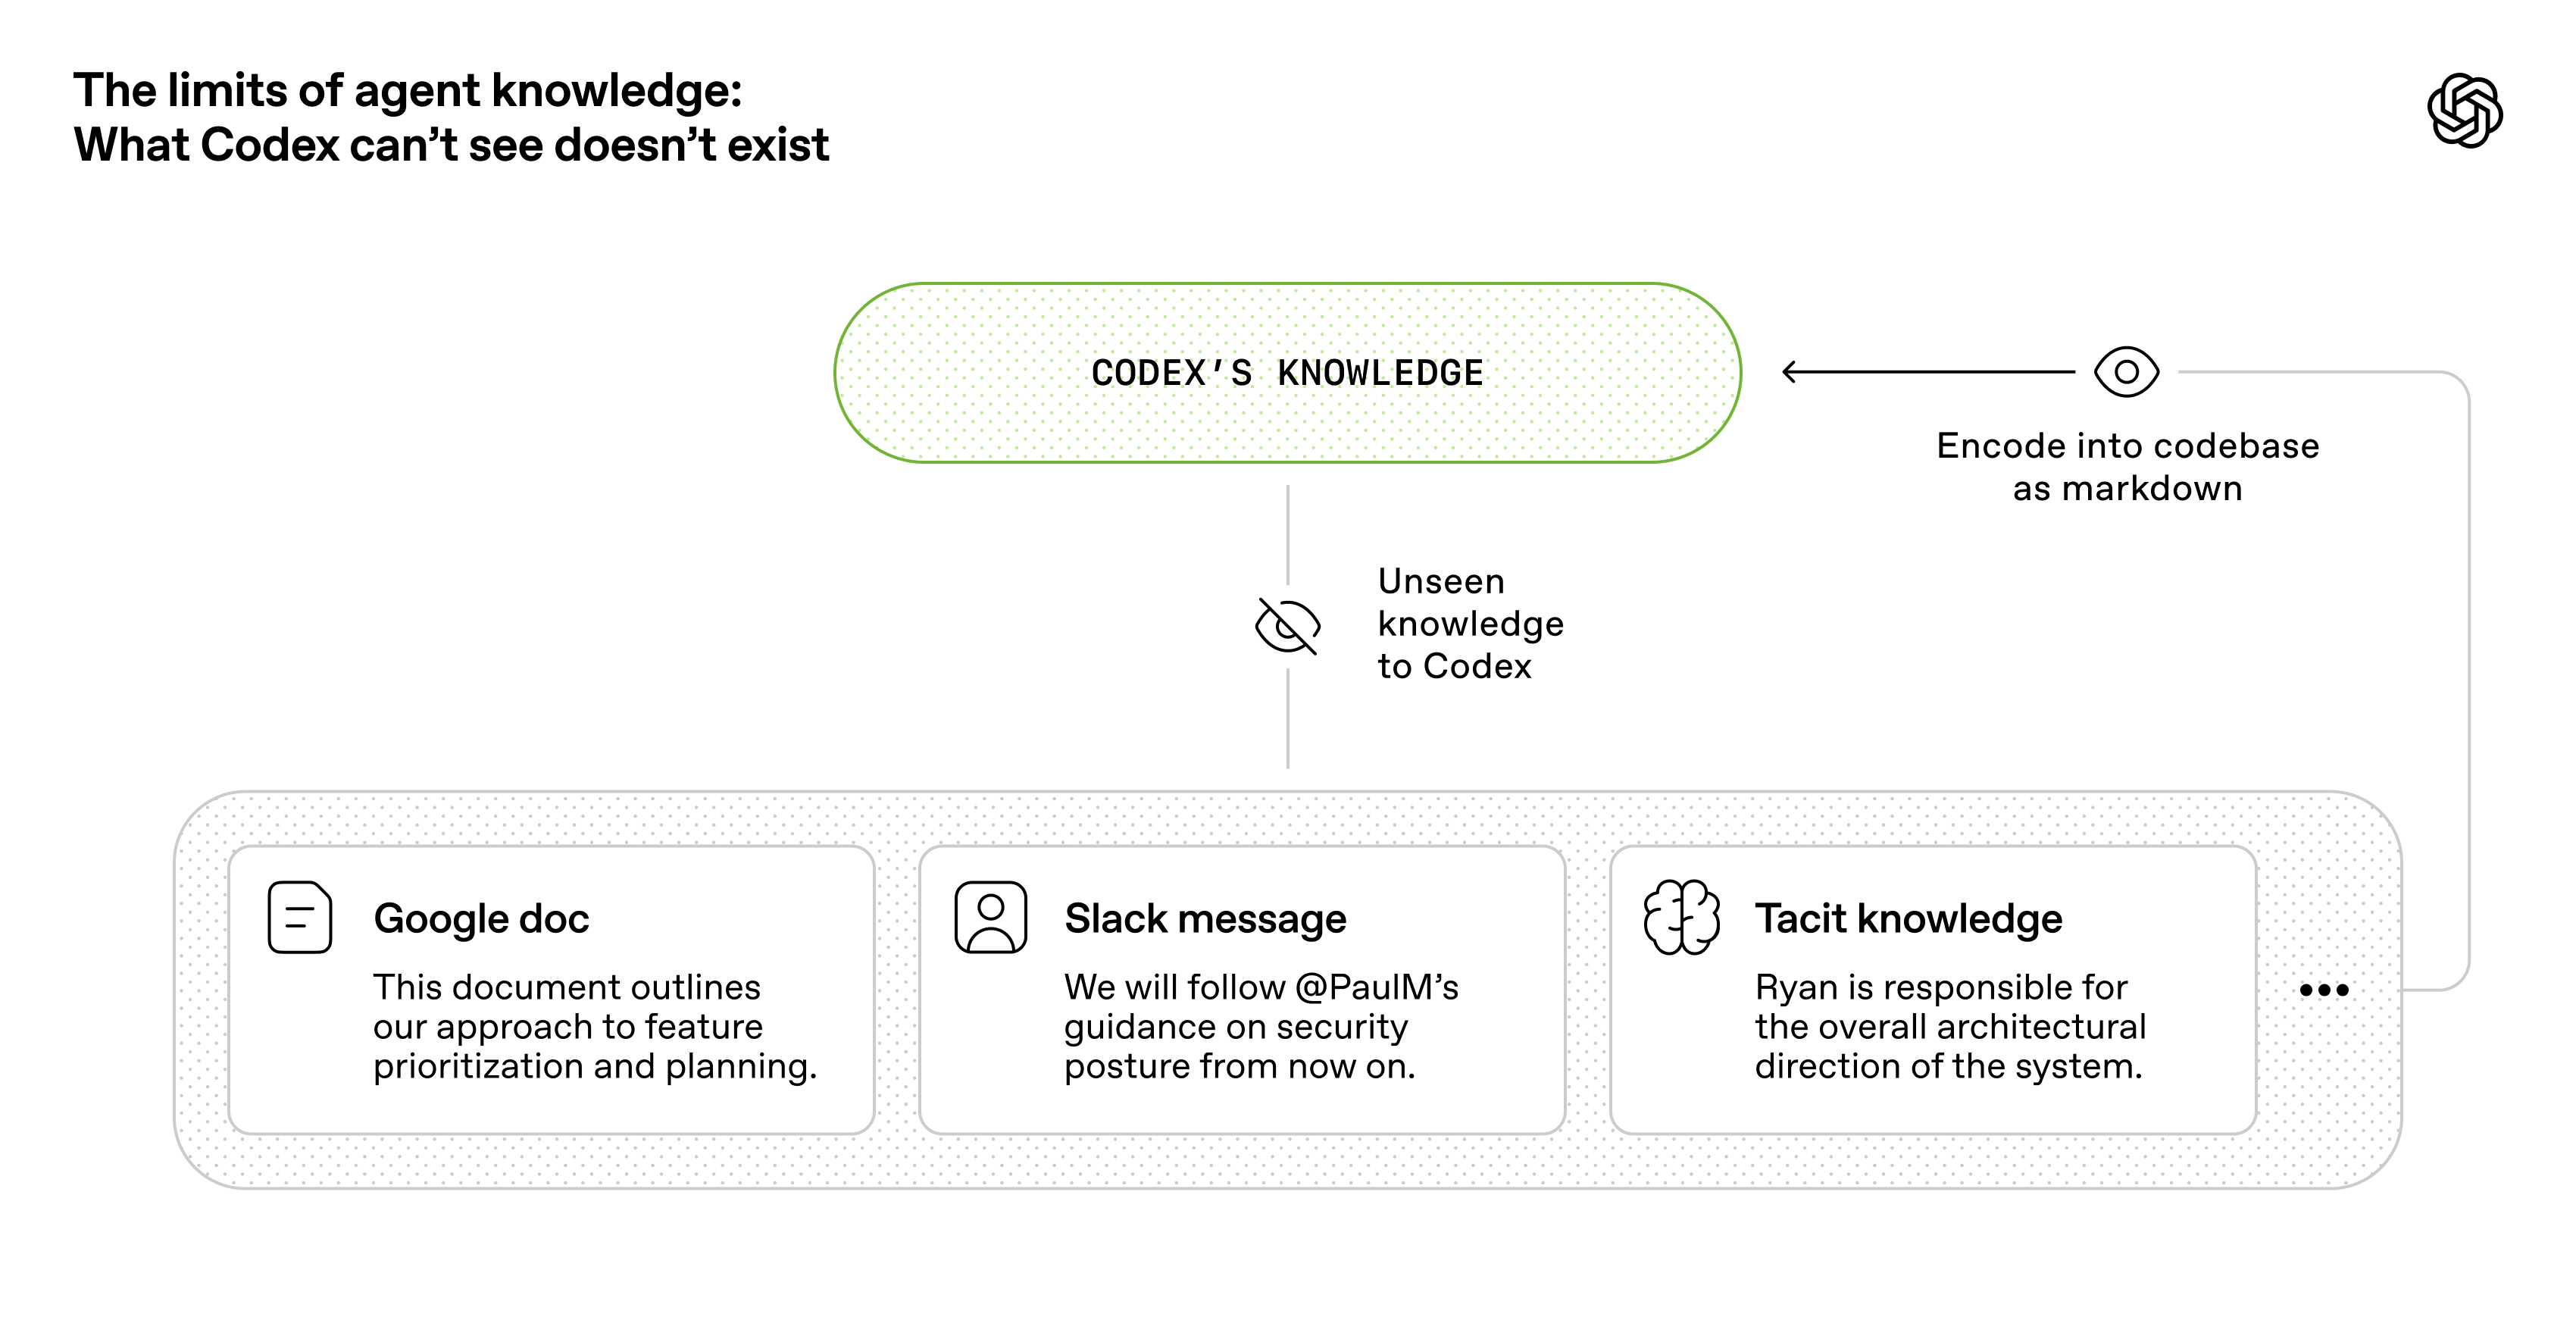
We learned that we needed to push more and more context into the repo over time. That Slack discussion that aligned the team on an architectural pattern? If it isn’t discoverable to the agent, it’s illegible in the same way it would be unknown to a new hire joining three months later.
我们发现,随着时间推移,得把越来越多的上下文推进仓库里。那次让团队在某个架构模式上达成一致的 Slack 讨论呢?如果 Agent 找不到它,它对 Agent 来说就是不可读的,就像三个月后才入职的新人根本不会知道有过这么一回事。
Giving Codex more context means organizing and exposing the right information so the agent can reason over it, rather than overwhelming it with ad-hoc instructions. In the same way you would onboard a new teammate on product principles, engineering norms, and team culture (emoji preferences included), giving the agent this information leads to better-aligned output.
给 Codex 更多上下文,意思是把对的信息组织好、暴露出来,让 Agent 能基于它推理,而不是拿一堆临时指令把它淹没。就像你会给新同事讲产品原则、工程规范和团队文化(包括大家爱用什么 emoji)一样,把这些信息告诉 Agent,它的产出也会更对路。
This framing clarified many tradeoffs. We favored dependencies and abstractions that could be fully internalized and reasoned about in-repo. Technologies often described as “boring” tend to be easier for agents to model due to composability, api stability, and representation in the training set. In some cases, it was cheaper to have the agent reimplement subsets of functionality than to work around opaque upstream behavior from public libraries. For example, rather than pulling in a generic p-limit-style package, we implemented our own map-with-concurrency helper: it’s tightly integrated with our OpenTelemetry instrumentation, has 100% test coverage, and behaves exactly the way our runtime expects.
这么一想,很多取舍就清楚了。我们偏好那些能完全在仓库内部消化、推理的依赖和抽象。常被说成「无聊」的技术,因为可组合、API 稳定、在训练集里出现得多,往往更容易被 Agent 建模。有时候,让 Agent 重新实现一部分功能,比绕开公共库里不透明的上游行为还省事。比如,我们没有引入一个通用的 p-limit 式的包,而是自己实现了一个带并发控制的 map 辅助函数:它和我们的 OpenTelemetry 埋点紧密集成,测试覆盖率 100%,行为也完全符合我们运行时的预期。
Pulling more of the system into a form the agent can inspect, validate, and modify directly increases leverage—not just for Codex, but for other agents (e.g. Aardvark) that are working on the codebase as well.
把系统更多的部分变成 Agent 能直接检查、验证和修改的形式,杠杆就更大了。受益的不只是 Codex,还有其他也在这个代码库上干活的 Agent(比如 Aardvark)。
Enforcing architecture and taste强制执行架构和品味
Documentation alone doesn’t keep a fully agent-generated codebase coherent. By enforcing invariants, not micromanaging implementations, we let agents ship fast without undermining the foundation. For example, we require Codex to parse data shapes at the boundary, but are not prescriptive on how that happens (the model seems to like Zod, but we didn’t specify that specific library).
光靠文档,没法让一个完全由 Agent 生成的代码库保持一致。我们强制的是不变量,不对具体实现事事过问,这样 Agent 能快速交付,又不会把地基挖坏。比如,我们要求 Codex 在边界处解析数据结构,但不规定具体怎么做(模型好像挺喜欢 Zod,不过我们并没有指定这个库)。
Agents are most effective in environments with strict boundaries and predictable structure, so we built the application around a rigid architectural model. Each business domain is divided into a fixed set of layers, with strictly validated dependency directions and a limited set of permissible edges. These constraints are enforced mechanically via custom linters (Codex-generated, of course!) and structural tests.
Agent 在边界严格、结构可预测的环境里最能发挥作用,所以我们围绕一个严格的架构模型来搭这个应用。每个业务领域都分成一组固定的层,依赖方向经过严格校验,允许的依赖边也只有有限的几种。这些约束靠自定义 linter(当然也是 Codex 生成的!)和结构测试机械地强制执行。
The diagram below shows the rule: within each business domain (e.g. App Settings), code can only depend “forward” through a fixed set of layers (Types → Config → Repo → Service → Runtime → UI). Cross-cutting concerns (auth, connectors, telemetry, feature flags) enter through a single explicit interface: Providers. Anything else is disallowed and enforced mechanically.
下图展示了这条规则:在每个业务领域(比如 App Settings)内部,代码只能沿着一组固定的层「向前」依赖(Types → Config → Repo → Service → Runtime → UI)。横切关注点(鉴权、连接器、遥测、功能开关)只能从一个明确的接口进来:Providers。其他依赖一律不允许,并且由机器强制执行。
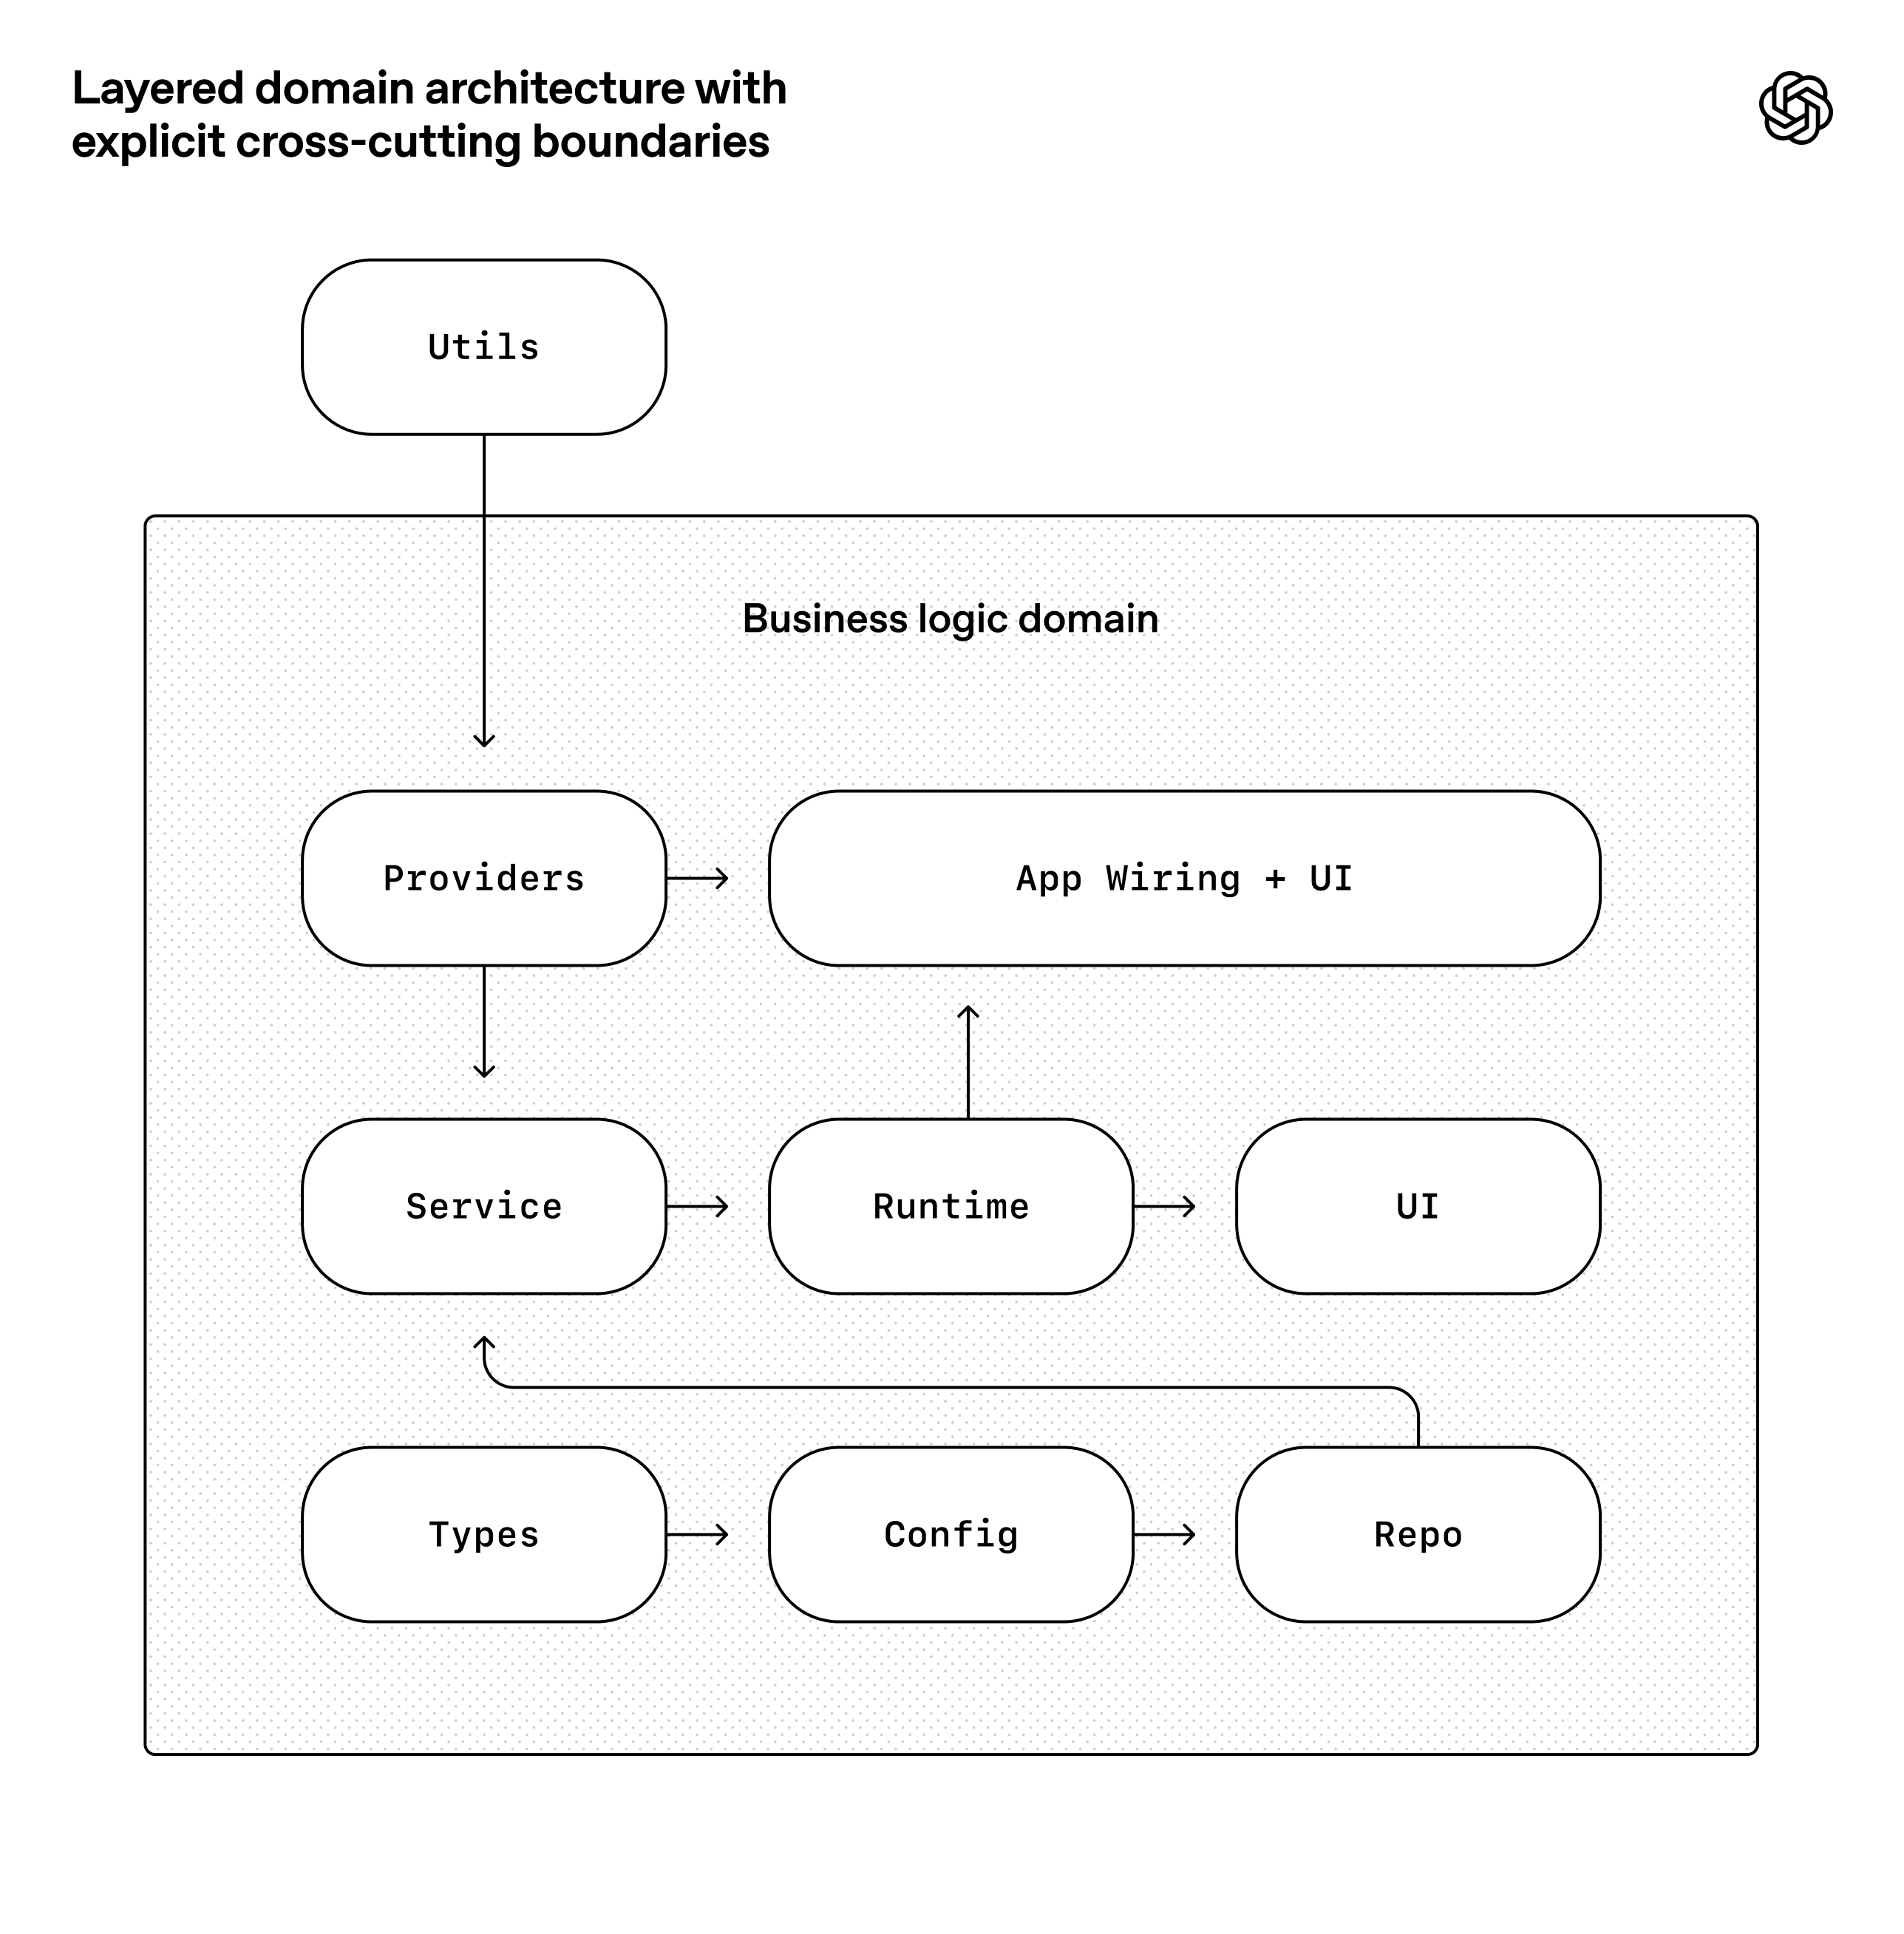
This is the kind of architecture you usually postpone until you have hundreds of engineers. With coding agents, it’s an early prerequisite: the constraints are what allows speed without decay or architectural drift.
这种架构,通常要等到你有几百个工程师时才会去做。有了编程 Agent,它成了早期就得有的前提:正是这些约束,让速度上去的同时,代码不会腐化,架构也不会跑偏。
In practice, we enforce these rules with custom linters and structural tests, plus a small set of “taste invariants.” For example, we statically enforce structured logging, naming conventions for schemas and types, file size limits, and platform-specific reliability requirements with custom lints. Because the lints are custom, we write the error messages to inject remediation instructions into agent context.
实际做法是用自定义 linter 和结构测试来强制执行这些规则,再加上一小组「品味不变量」。比如,我们用自定义 lint 静态地强制要求结构化日志、schema 和类型的命名规范、文件大小上限,以及特定平台的可靠性要求。因为 lint 是自己写的,报错信息我们也会专门写,把修复指引注入 Agent 的上下文。
In a human-first workflow, these rules might feel pedantic or constraining. With agents, they become multipliers: once encoded, they apply everywhere at once.
在以人为主的工作流里,这些规则可能显得吹毛求疵、束手束脚。但对 Agent 来说,它们是放大器:一旦写成规则,就在所有地方同时生效。
At the same time, we’re explicit about where constraints matter and where they do not. This resembles leading a large engineering platform organization: enforce boundaries centrally, allow autonomy locally. You care deeply about boundaries, correctness, and reproducibility. Within those boundaries, you allow teams—or agents—significant freedom in how solutions are expressed.
同时,我们也会讲清楚哪些地方的约束要紧,哪些地方不要紧。这很像带一个大型的工程平台组织:边界集中管控,局部放手自治。你非常在意边界、正确性和可复现性;在这些边界之内,团队(或者 Agent)怎么表达解决方案,有很大的自由。
The resulting code does not always match human stylistic preferences, and that’s okay. As long as the output is correct, maintainable, and legible to future agent runs, it meets the bar.
这样写出来的代码不一定合人的口味,这没关系。只要输出是正确的、可维护的,以后的 Agent 运行也看得懂,就算达标。
Human taste is fed back into the system continuously. Review comments, refactoring pull requests, and user-facing bugs are captured as documentation updates or encoded directly into tooling. When documentation falls short, we promote the rule into code
人的品味会持续反馈回系统。评审意见、重构的 pull request 和用户碰到的 bug,都会变成文档更新,或者直接写进工具里。文档管不住的时候,我们就把规则升级成代码。
Throughput changes the merge philosophy吞吐量改变了合并的理念
As Codex’s throughput increased, many conventional engineering norms became counterproductive.
Codex 的吞吐量上去之后,很多传统的工程规范反倒起了反作用。
The repository operates with minimal blocking merge gates. Pull requests are short-lived. Test flakes are often addressed with follow-up runs rather than blocking progress indefinitely. In a system where agent throughput far exceeds human attention, corrections are cheap, and waiting is expensive.
这个仓库里会卡住合并的门禁很少,pull request 的生命周期都很短。测试偶发失败(flake)一般是再跑一次来解决,而不是无限期地卡住进度。在一个 Agent 吞吐量远远超过人的注意力的系统里,纠错很便宜,等待很昂贵。
This would be irresponsible in a low-throughput environment. Here, it’s often the right tradeoff.
在低吞吐量的环境里,这么做是不负责任的。在这里,它往往是正确的取舍。
What “agent-generated” actually means「Agent 生成」到底指什么
When we say the codebase is generated by Codex agents, we mean everything in the codebase.
我们说代码库是 Codex Agent 生成的,指的是代码库里的一切。
Agents produce:
Agent 产出的东西包括:
- Product code and tests产品代码和测试
- CI configuration and release toolingCI 配置和发布工具
- Internal developer tools内部开发者工具
- Documentation and design history文档和设计历史
- Evaluation harnesses评测框架(evaluation harness)
- Review comments and responses评审意见和回复
- Scripts that manage the repository itself管理仓库本身的脚本
- Production dashboard definition files生产环境仪表盘的定义文件
Humans always remain in the loop, but work at a different layer of abstraction than we used to. We prioritize work, translate user feedback into acceptance criteria, and validate outcomes. When the agent struggles, we treat it as a signal: identify what is missing—tools, guardrails, documentation—and feed it back into the repository, always by having Codex itself write the fix.
人始终在回路里,只是工作所在的抽象层和以前不一样了。我们排工作优先级,把用户反馈转成验收标准,再验证结果。Agent 卡住的时候,我们把它当成一个信号:找出缺了什么(工具、护栏、文档),再补回仓库里,而且一律让 Codex 自己来写这个修复。
Agents use our standard development tools directly. They pull review feedback, respond inline, push updates, and often squash and merge their own pull requests.
Agent 直接用我们的标准开发工具。它们拉取评审反馈、逐行回复、推送更新,还经常自己 squash 并合并自己的 pull request。
Increasing levels of autonomy越来越高的自主程度
As more of the development loop was encoded directly into the system—testing, validation, review, feedback handling, and recovery—the repository recently crossed a meaningful threshold where Codex can end-to-end drive a new feature.
随着越来越多的开发环节(测试、验证、评审、处理反馈、故障恢复)被直接写进系统,这个仓库最近跨过了一道有意义的门槛:Codex 已经能端到端地推进一个新功能了。
Given a single prompt, the agent can now:
现在只要一条提示词,Agent 就能:
- Validate the current state of the codebase验证代码库的当前状态
- Reproduce a reported bug复现一个被报告的 bug
- Record a video demonstrating the failure录一段视频演示这个故障
- Implement a fix实现修复
- Validate the fix by driving the application操作应用来验证修复
- Record a second video demonstrating the resolution再录一段视频演示问题已经解决
- Open a pull request开一个 pull request
- Respond to agent and human feedback回应 Agent 和人的反馈
- Detect and remediate build failures发现并修好构建失败
- Escalate to a human only when judgment is required只在需要判断时才上报给人
- Merge the change合并改动
This behavior depends heavily on the specific structure and tooling of this repository and should not be assumed to generalize without similar investment—at least, not yet.
这种表现在很大程度上依赖这个仓库特定的结构和工具。没有类似的投入,别指望它能照搬到别处,至少现在还不行。
Entropy and garbage collection熵与垃圾回收
Full agent autonomy also introduces novel problems. Codex replicates patterns that already exist in the repository—even uneven or suboptimal ones. Over time, this inevitably leads to drift.
Agent 完全自主也会带来新问题。Codex 会照搬仓库里已有的模式,哪怕是参差不齐、不够好的模式。时间一长,必然会跑偏。
Initially, humans addressed this manually. Our team used to spend every Friday (20% of the week) cleaning up “AI slop.” Unsurprisingly, that didn’t scale.
一开始是人手动处理。我们团队以前每周五(一周 20% 的时间)都在清理「AI slop」(AI 生成的垃圾代码)。不出所料,这种做法撑不住规模。
Instead, we started encoding what we call “golden principles” directly into the repository and built a recurring cleanup process. These principles are opinionated, mechanical rules that keep the codebase legible and consistent for future agent runs. For example: (1) we prefer shared utility packages over hand-rolled helpers to keep invariants centralized, and (2) we don’t probe data “YOLO-style”—we validate boundaries or rely on typed SDKs so the agent can’t accidentally build on guessed shapes. On a regular cadence, we have a set of background Codex tasks that scan for deviations, update quality grades, and open targeted refactoring pull requests. Most of these can be reviewed in under a minute and automerged.
后来,我们开始把所谓的「黄金原则」直接写进仓库,并建了一个定期执行的清理流程。这些原则是带着明确立场的机械规则,让代码库对以后的 Agent 运行保持可读、一致。比如:(1)我们更愿意用共享的工具包,而不是手搓辅助函数,好让不变量集中在一处;(2)我们不「YOLO 式」地去试探数据,而是在边界处校验,或者依赖带类型的 SDK,这样 Agent 就不会不小心在猜出来的数据结构上继续搭东西。我们还有一组后台 Codex 任务按固定节奏运行,扫描偏离规则的地方,更新质量评分,开有针对性的重构 pull request。这些 PR 大部分一分钟内就能看完,然后自动合并。
This functions like garbage collection. Technical debt is like a high-interest loan: it’s almost always better to pay it down continuously in small increments than to let it compound and tackle it in painful bursts. Human taste is captured once, then enforced continuously on every line of code. This also lets us catch and resolve bad patterns on a daily basis, rather than letting them spread in the code base for days or weeks.
这就像垃圾回收。技术债像一笔高息贷款:持续地小额偿还,几乎总比任它利滚利、再痛苦地集中还要好。人的品味只需要捕捉一次,之后就在每一行代码上持续执行。这样我们每天都能把坏模式揪出来解决掉,不会任它们在代码库里蔓延几天甚至几周。
What we’re still learning我们还在摸索的事
This strategy has so far worked well up through internal launch and adoption at OpenAI. Building a real product for real users helped anchor our investments in reality and guide us towards long-term maintainability.
到目前为止,从内部发布到在 OpenAI 内部推开使用,这套策略都运转得不错。给真实用户做一个真实的产品,让我们的投入始终落在实处,也引着我们朝长期可维护的方向走。
What we don’t yet know is how architectural coherence evolves over years in a fully agent-generated system. We’re still learning where human judgment adds the most leverage and how to encode that judgment so it compounds. We also don’t know how this system will evolve as models continue to become more capable over time.
我们还不知道的是,在一个完全由 Agent 生成的系统里,架构的一致性放到几年的尺度上会怎么演变。人的判断在哪里最能发挥杠杆作用、怎么把这种判断编码下来让它不断累积,我们也还在摸索。随着模型越来越强,这套系统会怎么演变,我们同样不知道。
What’s become clear: building software still demands discipline, but the discipline shows up more in the scaffolding rather than the code. The tooling, abstractions, and feedback loops that keep the codebase coherent are increasingly important.
已经清楚的是:做软件依然需要纪律,只是这种纪律更多体现在脚手架上,而不是代码里。让代码库保持一致的工具、抽象和反馈回路,正变得越来越重要。
Our most difficult challenges now center on designing environments, feedback loops, and control systems that help agents accomplish our goal: build and maintain complex, reliable software at scale.
我们现在最难的挑战,集中在设计环境、反馈回路和控制系统上,让它们帮 Agent 实现我们的目标:大规模地构建和维护复杂、可靠的软件。
As agents like Codex take on larger portions of the software lifecycle, these questions will matter even more. We hope that sharing some early lessons helps you reason about where to invest your effort so you can just build things.
随着 Codex 这样的 Agent 承担起软件生命周期里越来越大的部分,这些问题会变得更重要。希望我们分享的这些早期经验,能帮你想清楚该把精力投在哪里,这样你就可以直接动手做东西。
Acknowledgements致谢
Special thanks to Victor Zhu and Zach Brock who contributed to the post, as well as to the entire team that built this new product.
特别感谢为这篇文章出力的 Victor Zhu 和 Zach Brock,也感谢做出这个新产品的整个团队。